Tencent's DSpine speeds up Qwen3.8-27B about 3x, and Anthropic explains how Claude's agent memory works
Window · 2026.11.07 06:43 – 11.09 06:43 KST
Here's today's news. This window covered Saturday and Sunday, and no new models or major products shipped. So we picked one thing you can download and run today, plus one write-up that teams building agents should read.
Tencent posted DSpine to Hugging Face, a speculative-decoding draft model that speeds up generation on Qwen3.8-27B. It plugs into SGLang with one command. On replayed agent workloads Tencent measured 2.7 to 3.8 times the throughput of plain decoding.
We also added a late catch: Anthropic's engineering post on agent memory, published early on November 7 (KST). It fell inside our previous issue's window, and we missed it.
At a glance
- 01 Tencent DSpine: a speculative-decoding draft model that runs Qwen3.8-27B about 3x faster Tencent GA
- 02 [Late catch] Anthropic on agent memory: letting Claude reread its work logs and fix its notes with "dreaming" Anthropic Research
Today's items
Tencent DSpine: a speculative-decoding draft model that runs Qwen3.8-27B about 3x faster
What is it?
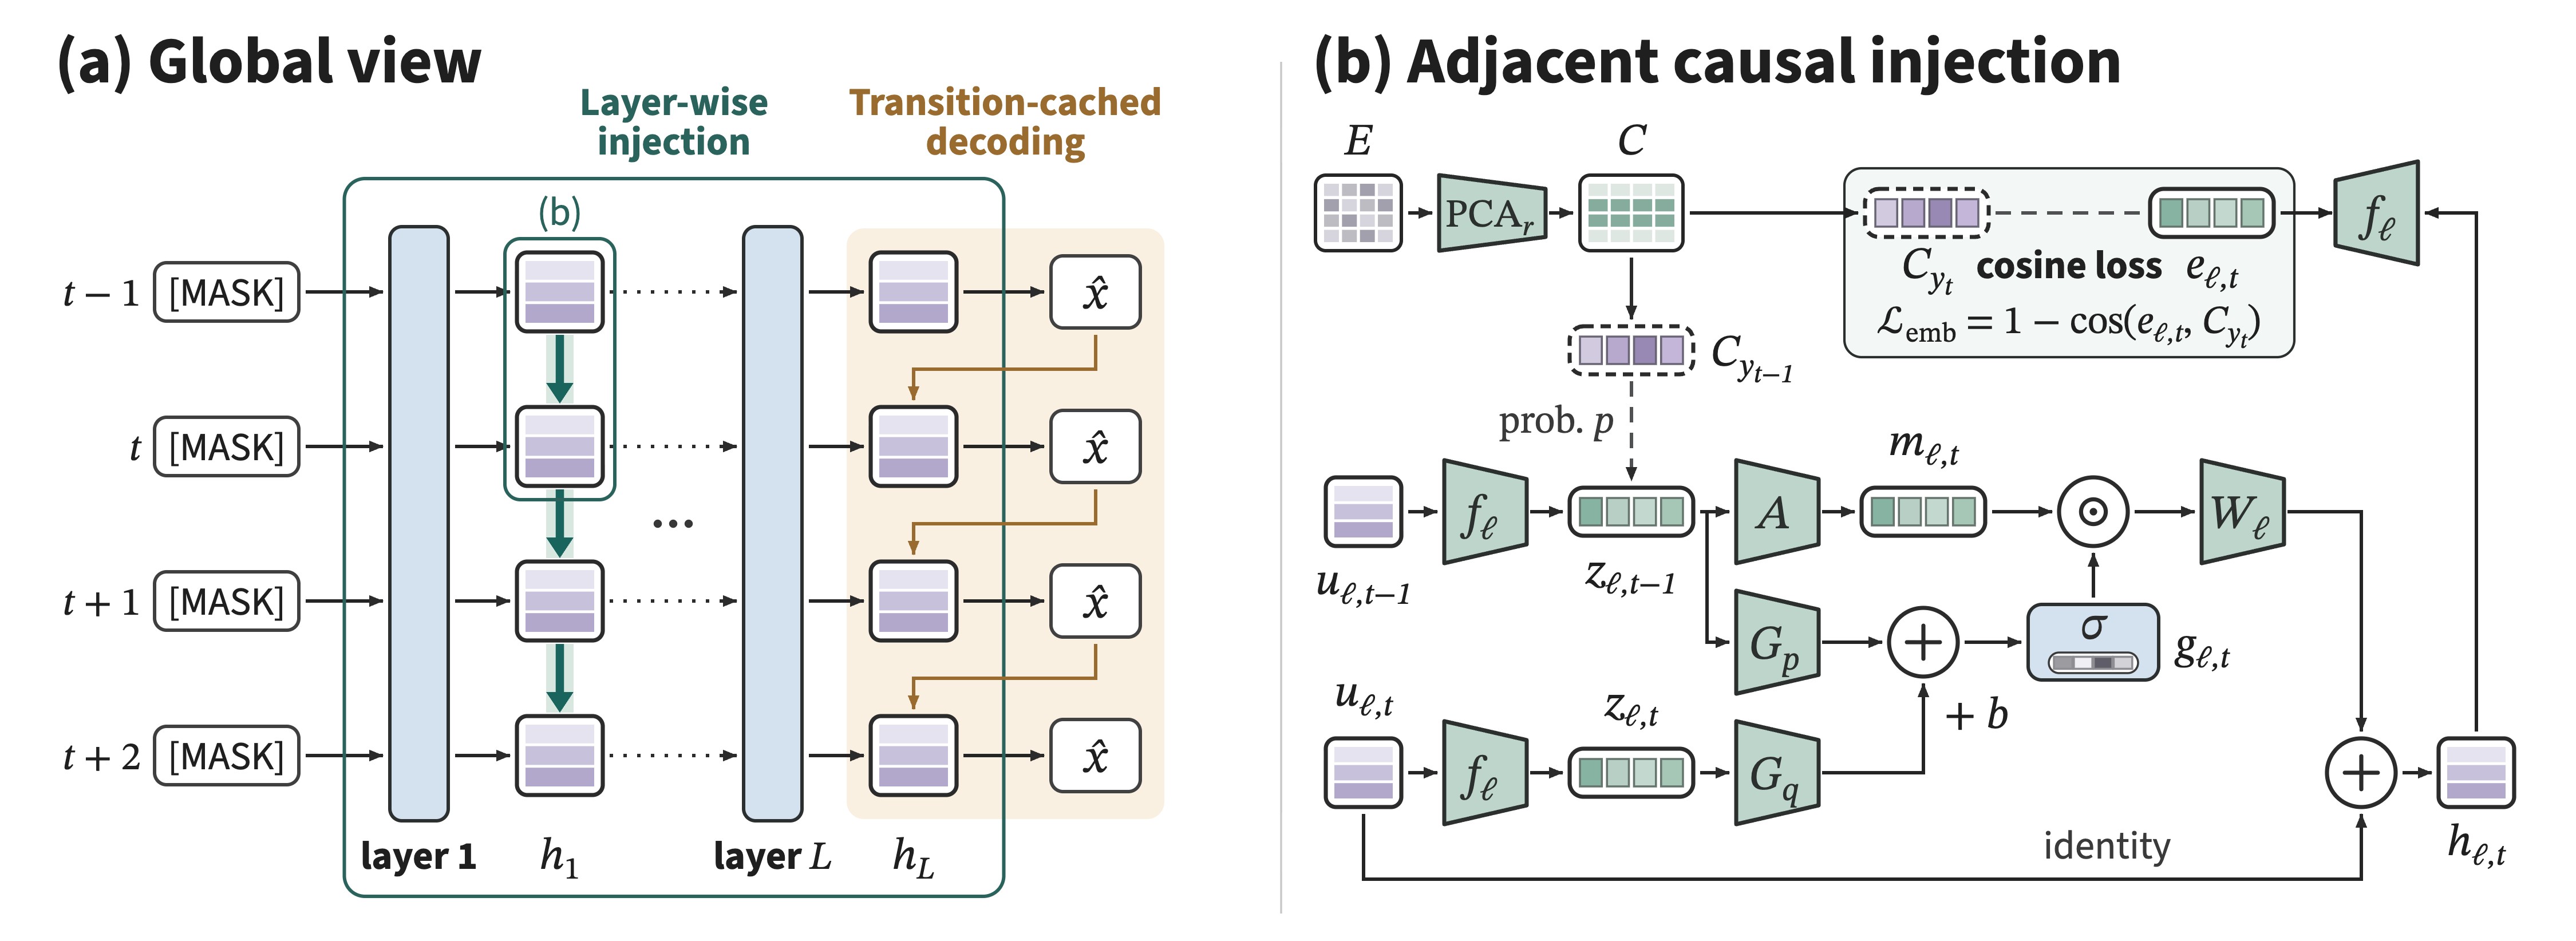
Speculative decoding speeds up generation by letting a small draft model guess several upcoming tokens, which the large model then checks in a single pass. DSpine is Tencent's drafting method: it guesses 16 tokens at once, and each layer passes predicted features to neighboring positions so the guesses still account for token order. The new release is a five-layer draft model for Qwen3.8-27B under Apache 2.0. Install the SGLang plugin from the repo, then point the server at the draft model.
git clone https://github.com/tencent/dspine.git && cd dspine && python -m pip install -e .
sglang serve --model-path /path/to/Qwen3.8-27B --speculative-algorithm DSPINE --speculative-draft-model-path tencent/Qwen3.8-27B-DSpine-b16 --speculative-num-draft-tokens 16 --trust-remote-codeThe repo README lists the other flags Qwen3.8-27B needs, including ReplaySSM and dynamic verification tuning.
Why does it matter?
Many teams run Qwen3.8-27B on a single GPU as a coding agent, so faster responses on the same hardware are easy to notice. Replaying coding, web and office agent conversations plus SWE-bench Pro, Tencent measured 2.7 to 3.8 times the throughput of plain decodingVendor claim, with more tokens accepted per step than the existing open DFlash2 drafterVendor claim. Output quality stays the same and only speed changes, so it's worth a test if you're trying to cut serving costs.
Maturity
GAWeights and inference code are both public and ready to download. You'll need SGLang 0.5.22, CUDA and Python 3.11 or later, and every number so far comes from Tencent's own runs.
How to track it
- Independent numbers: watch the SGLang community and GitHub issues for speedups measured on other GPUs and real production traffic.
- Wider support: check whether vLLM support or drafters for other models show up in the tencent/dspine collection on Hugging Face.
- Apple Silicon: follow the News section of the GitHub repo to see if the MLX path extends to Qwen3.8-27B.
[Late catch] Anthropic on agent memory: letting Claude reread its work logs and fix its notes with "dreaming"
What is it?
Anthropic wrote up its experiments on giving Claude memory that carries across sessions. Two pieces matter most. First, Claude writes important details to a memory folder as it works. Second, during idle time it rereads past transcripts to correct and merge those notes, a step Anthropic calls dreaming. The experiments ran on Claude Managed Agents with a memory folder that persisted between sessions.
Why does it matter?
The most common problem teams hit when they add memory to an agent is a wrong note that sticks around and causes the same mistake again. According to the post, dreaming let Claude check notes against the original logs and fix bad ones, and on a set of questions about a company's documents, scaling dreaming from 2 sessions to 128 raised the score from 13% to 48%Vendor claim. Another useful point for design: telling Claude what memory is for worked better than spelling out how to use it.
Maturity
ResearchThis is an engineering post about internal experiments, not a product launch. There's no separate API or setting called dreaming.
How to track it
- Productization: watch the Claude Managed Agents docs and the Claude Platform release notes for background memory cleanup like dreaming shipping as a feature.
- Benchmark release: follow the Anthropic engineering blog to see if CL-Bench 1.0, used in the post, becomes public so other models can be compared.
Bottom line
Research log
Sources checked (✓ checked / – nothing relevant / ✕ could not access)
- ✓Hugging Face API · Tencent/DSpine GitHub — Qwen3.8-27B-DSpine-b16 created Nov 7 14:20 UTC, inference commit 15:57 UTC → selected. No new models in 48h from major lab HF orgs (Qwen, DeepSeek, Google, Meta, Mistral, Microsoft, NVIDIA, etc.)
- ✓Anthropic engineering blog · X @AnthropicAI — Nov 6 21:16 UTC agent memory post → missed in the previous window, selected as [Late catch]. Nov 7 Science Blog post on scientific modeling is commentary → skipped
- ✓Claude Platform release notes · Claude Code releases — Latest Nov 5 (IP allowlist, already covered). Claude Code v2.1.319 at Nov 6 17:04 UTC is outside the window
- ✓OpenAI API changelog · ChatGPT & Codex changelog · openai/codex releases — API: last entry Nov 5 GPT-6 Cyber. Codex CLI 0.167.0 (Nov 6 01:40 UTC) outside window; 0.169.0-alpha.3 (Nov 7) is an alpha → skipped
- ✓OpenAI research 'A thousand fewer paths to root' — Published Nov 4 (948 Linux LPEs) → outside window, weekend coverage was re-reporting
- ✓Gemini API changelog · Google blog · Google for Developers blog — Nov 6 gemini-embedding-2-preview auto-routing (minor), Omni 1.2 Flash (covered) → nothing new. A2UI Express (Oct 27) and Markdown in Docs (Oct 26) outside window
- ✓Google DeepMind (X @GoogleDeepMind) — Nov 6 17:20 UTC RSA-1024 cryptanalysis research → outside window, research result → skipped
- ✓Ant Ling developer changelog — Nov 5 Ling-3.2-flash (560B multimodal, API) → outside window. Late-catch candidate, but one per day, so Anthropic's post was chosen
- ✓Nous Research blog · HF — Nov 6 15:00 UTC Arete-27B (values fine-tune of Qwen3.8-27B) → outside window, not used as late catch
- ✓Hugging Face blog — Nov 6 harness adapters (community post, new adapters still training) → skipped. Cosmos 3 and ToyBlocks predate the last issue
- ✓GitHub changelog — Latest Nov 6 (Copilot code review API, Slack/Teams GA) → outside window
- ✓Mistral news · X @MistralAI — Nov 5 Studio (covered), Nov 6 16:38 UTC Voxtral 3 end-of-turn detection (re-promoting an Oct 20 feature) → skipped
- ✓commandline.microsoft.com — Nov 6 ThinkingBox part 2 (evaluation/RL post) → outside window
- ✓Apple ML research (arXiv HALO) — Submitted Nov 4 → outside window
- ✓X @karpathy — Nov 7 17:07 UTC TristanTube (variant of HackerTube, covered Nov 2) → skipped
- ✓X @OpenAIDevs — Nov 7 00:02 UTC Showcase tab promo for the Developers plugin (no docs to back it) → skipped. Nov 8 20:04 UTC 'Tomorrow.' teaser → watch item
- ✓X @thsottiaux · @reach_vb — Nov 8 explainer on Pro plan usage multiples → existing policy, skipped
- ✓X @sama · @claudeai · @bcherny · @OfficialLoganK — No new announcements in 48h (latest Nov 4–6)
- ✓X @simonw · @_akhaliq — Mostly paper links, nothing to select
- ✓X @Alibaba_Qwen · @deepseek_ai · @xai (→ @SpaceXSI) — Qwen Nov 6 12:00 UTC teaser only ('The becoming begins'); no new DeepSeek or xAI posts
- –Other X accounts (@alexalbert__, @_catwu, @demishassabis, @ylecun, @AndrewYNg, @hardmaru, @swyx, @jeremyphoward, @rasbt, @ClementDelangue, @AIatMeta, @mustafasuleyman) — Not opened directly for time; web search found no new launches in 48h
- ✕LinkedIn (Andrew Ng, Satya Nadella, etc.) — Not opened this run
- ✓Swil-News Nov 7 and Nov 8 digests — Used for back-tracing → primary sources confirmed for OpenAI LPE, METR, DeepMind RSA, Ling-3.2-flash, Apple HALO; all outside window. Shared robots.txt training opt-out skipped (Google post is from October)
- ✓TechCrunch AI — Nov 7–8 stories were NVIDIA and data-center politics, no product launches
- ✕aiweekly.co daily edition — Nov 7 and Nov 8 editions return 404
- ✓llm-stats.com release tracker — Latest Nov 5 Inkling 2 Small (covered) → nothing new
- ✓GeekNews — #2 Anthropic memory post (selected). Pangram Image 1.0 and Linum P-JiT are Nov 4 → outside window
- ✓GitHub Trending (daily) — meta/astryx (+863, created in January), vercel-labs/agent-browser and others are existing projects → not new launches
- –AWS · NVIDIA · Meta · Apple newsrooms — Web search found no new models or tools in 48h
Generated: