Tencent DSpine: a speculative-decoding draft model that runs Qwen3.8-27B about 3x faster
What is it?
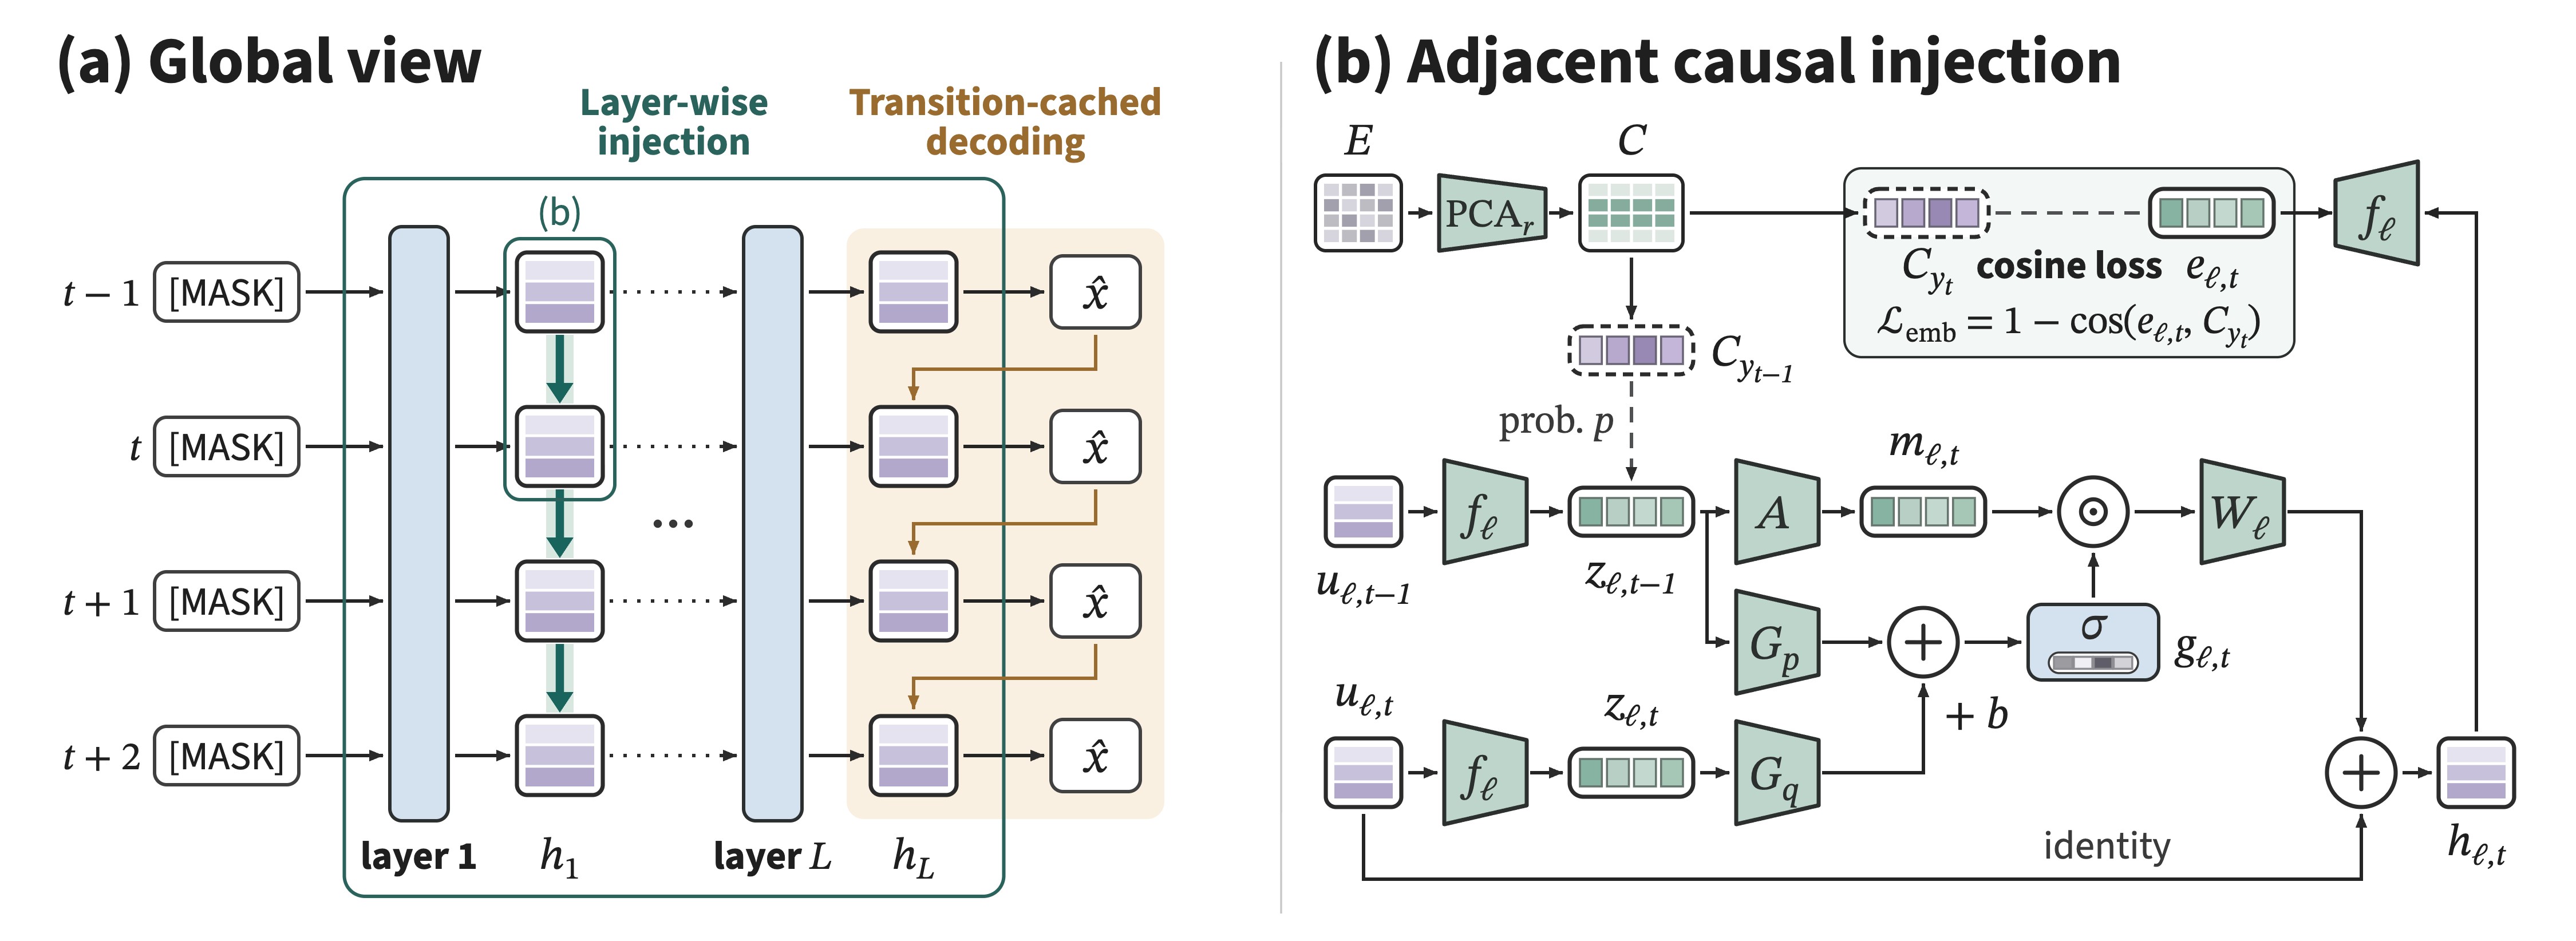
Speculative decoding speeds up generation by letting a small draft model guess several upcoming tokens, which the large model then checks in a single pass. DSpine is Tencent's drafting method: it guesses 16 tokens at once, and each layer passes predicted features to neighboring positions so the guesses still account for token order. The new release is a five-layer draft model for Qwen3.8-27B under Apache 2.0. Install the SGLang plugin from the repo, then point the server at the draft model.
git clone https://github.com/tencent/dspine.git && cd dspine && python -m pip install -e .
sglang serve --model-path /path/to/Qwen3.8-27B --speculative-algorithm DSPINE --speculative-draft-model-path tencent/Qwen3.8-27B-DSpine-b16 --speculative-num-draft-tokens 16 --trust-remote-codeThe repo README lists the other flags Qwen3.8-27B needs, including ReplaySSM and dynamic verification tuning.
Why does it matter?
Many teams run Qwen3.8-27B on a single GPU as a coding agent, so faster responses on the same hardware are easy to notice. Replaying coding, web and office agent conversations plus SWE-bench Pro, Tencent measured 2.7 to 3.8 times the throughput of plain decodingVendor claim, with more tokens accepted per step than the existing open DFlash2 drafterVendor claim. Output quality stays the same and only speed changes, so it's worth a test if you're trying to cut serving costs.
Maturity
GAWeights and inference code are both public and ready to download. You'll need SGLang 0.5.22, CUDA and Python 3.11 or later, and every number so far comes from Tencent's own runs.
How to track it
- Independent numbers: watch the SGLang community and GitHub issues for speedups measured on other GPUs and real production traffic.
- Wider support: check whether vLLM support or drafters for other models show up in the tencent/dspine collection on Hugging Face.
- Apple Silicon: follow the News section of the GitHub repo to see if the MLX path extends to Qwen3.8-27B.